Research notes
Long-form accounts of published papers: the question behind each one, how we tested it, what the evidence shows, and what it leaves open.
-
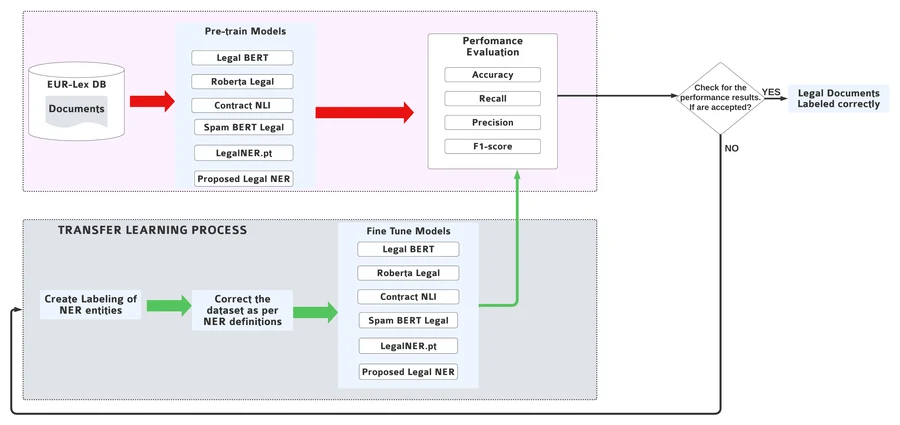
Can Transformers Reliably Anonymize Legal Documents?
Adapting BERT to legal language lifted entity-level F1 from 93.6% for the best legal-domain baseline to 99.4% on held-out EU judgments. This note follows the experiments behind that number, and explains why a 99% F1 score still does not make redaction reliable on its own.
Based on Karamitsos, Roufas, Al-Hussaeni & Kanavos, Frontiers in Artificial Intelligence, 2025
-
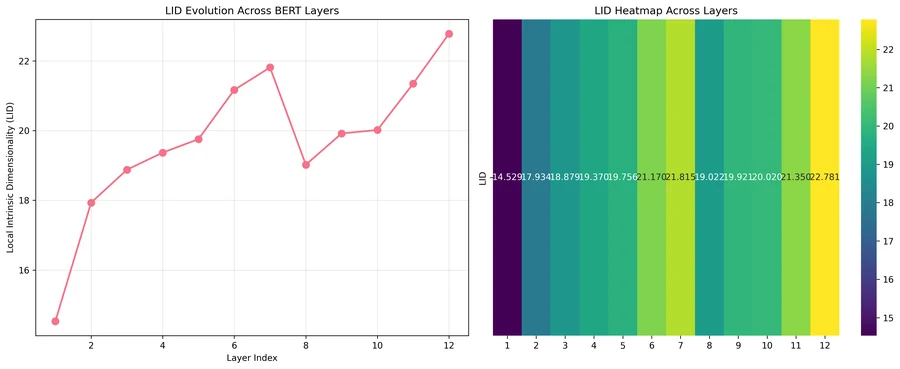
Do Deeper Transformer Layers Actually Explain Better?
The intrinsic dimensionality of BERT’s representations rises by 57% from the first layer to the last, with a sharp drop at layer 8, a result that reproduces exactly from public code. Whether that makes explanations better is a separate question, and one we have not yet answered.
Based on Roufas, Kanavos, Karamitsos, Al-Hussaeni & Maragoudakis, IEEE BigData 2025
-
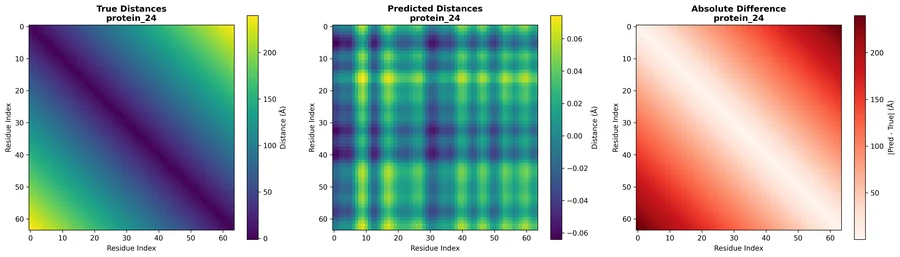
Can We Make Protein-Structure Prediction More Efficient with Linear Attention?
Linear attention removes the quadratic cost that limits transformers on long protein chains. We paired a Performer with evolutionary profiles to predict distances and angles. This note explains the idea, and reads the experiment’s own figures to show what the model did and did not learn.
Based on Roufas, Karamitsos, Al-Hussaeni, Gerogiannis & Kanavos, ICTA 2025, Springer LNNS